


The fastest way to run GGUF models on Apple Silicon.
gmlx is a local inference platform. You can chat with an open model in the terminal or your browser, serve it over OpenAI and Anthropic compatible APIs, and connect a coding agent to it. You can also talk to it by voice, build a local RAG stack on it and fine-tune it with LoRA.
It runs the community's K-quant and IQ-quant GGUF builds exactly as published. Those formats are the most accurate open quants at a given file size, and the companion project mlx-kquant supplies the Metal kernels that run them natively on Apple's MLX framework.
On the same file gmlx benchmarks faster than llama.cpp, and the gap is widest at the long contexts that coding agents and long sessions use. A mixture-of-experts model bigger than RAM still runs, by streaming its experts from disk.
Migrating from other tools says what carries over from llama.cpp, Ollama and LM Studio.

Higher is faster, and depth is the number of tokens already in the context. The per-model charts and the method behind them are in Benchmarks.
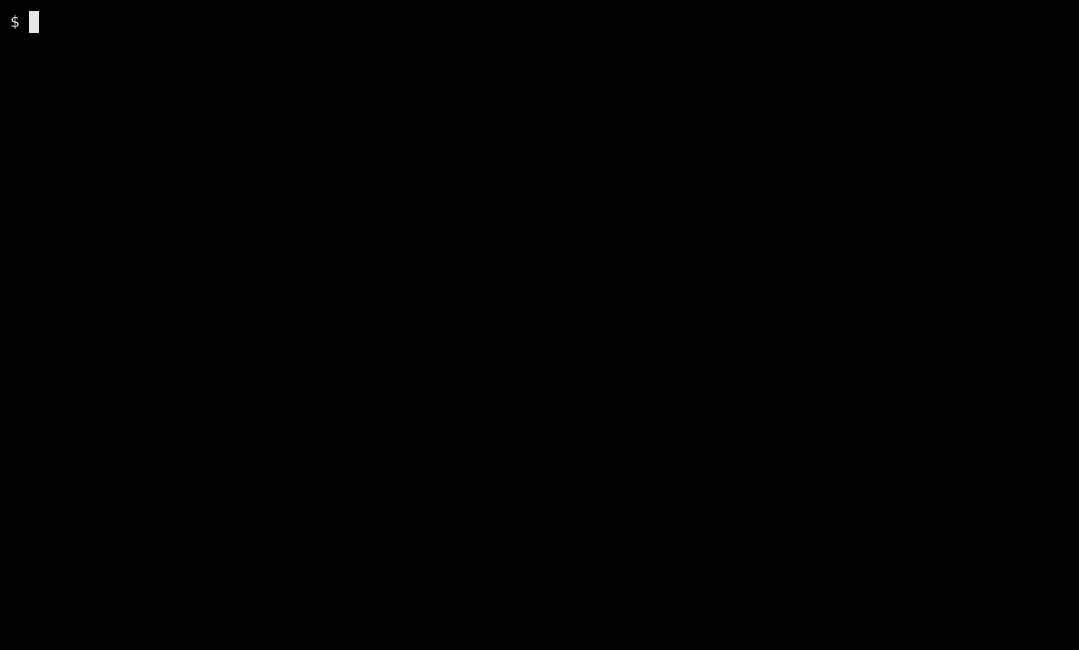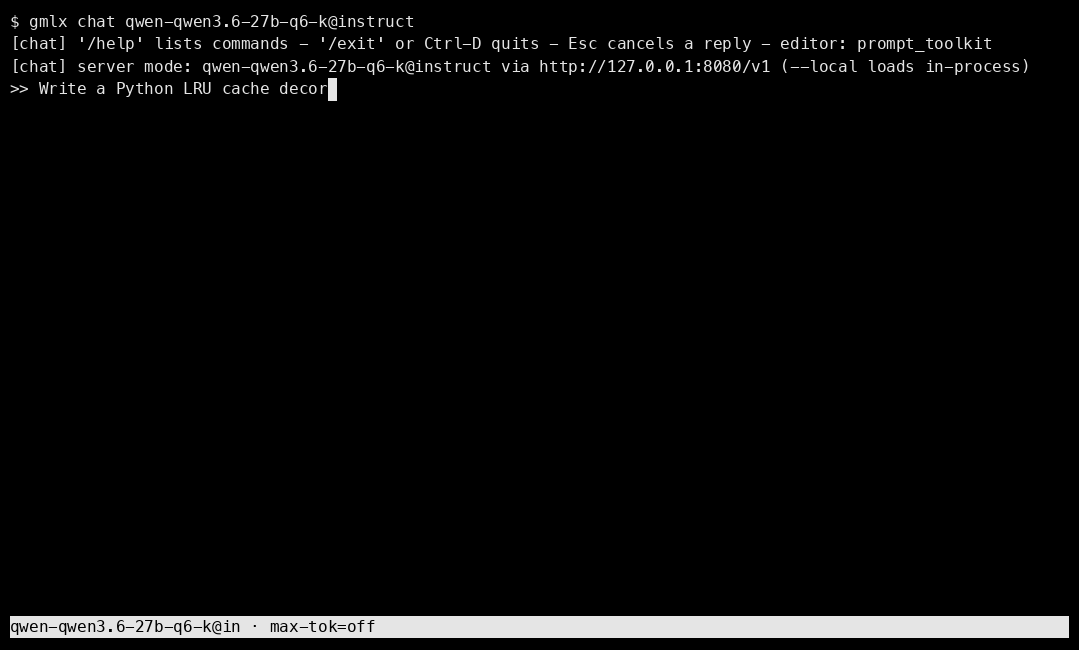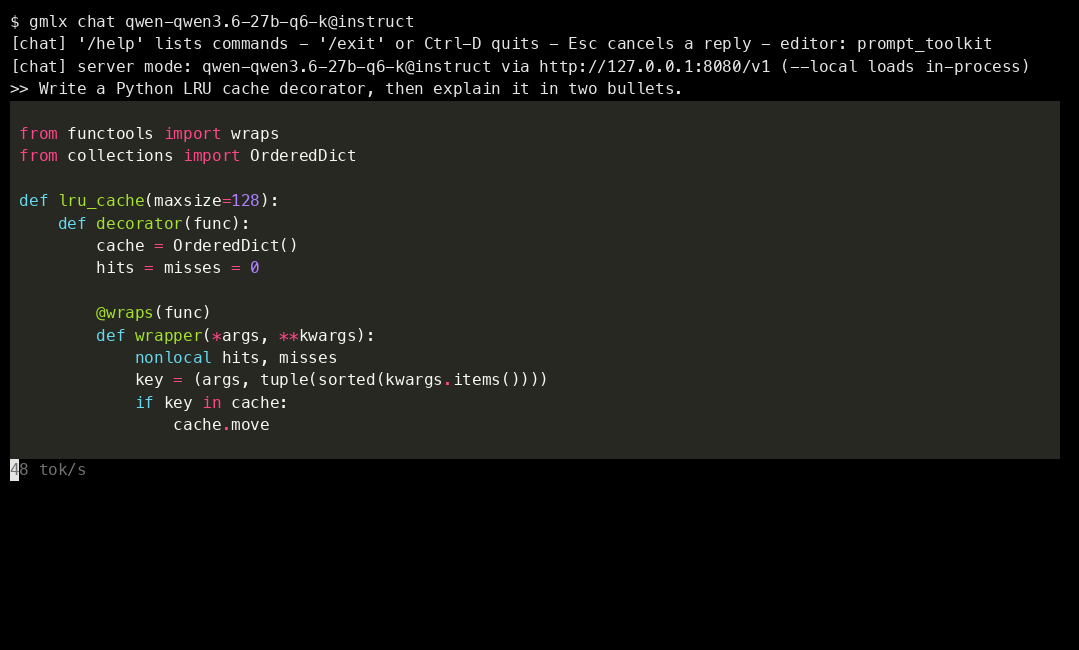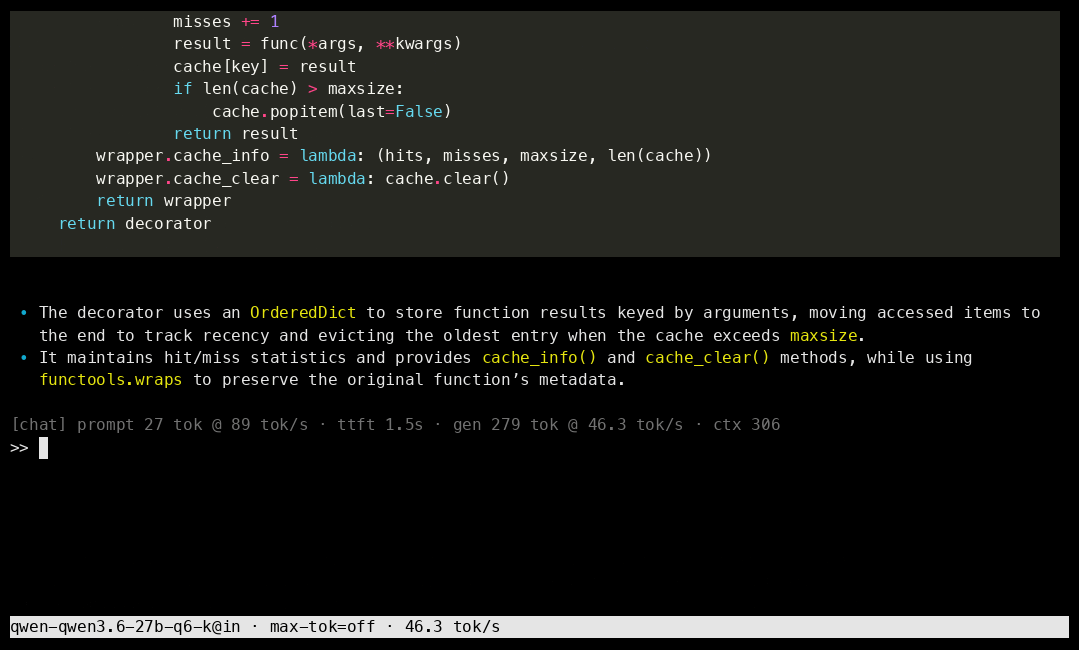
The recording runs at true speed, with a 27B model resident in a local server answering at 46 tokens per second.
gmlx needs an Apple Silicon Mac with macOS 26.2 or newer. Intel Macs and Linux are not supported. Install with Homebrew, then create a configuration file and download a model:
brew install asher/gmlx/gmlx

gmlx init --models-dir ~/models
gmlx pull hf:unsloth/Qwen3.8-27B-GGUF/Qwen3.8-27B-UD-Q6_K.gguf
gmlx run  qwen3.8-27b-ud-q6 --prompt "Explain entropy in one paragraph."
gmlx chat qwen3.8-27b-ud-q6
gmlx serve

curl localhost:8080/v1/chat/completions -d \
  '{"model": "qwen3.8-27b-ud-q6", "messages": [{"role": "user", "content": "hi"}]}'
gmlx launch pi --model qwen3.8-27b-ud-q6
gmlx init writes the configuration file. pull downloads into the folder
that the file names and adds the model under the id qwen3.8-27b-ud-q6,
which every command then accepts in place of a path. serve starts the
server in the background on port 8080, and launch connects the pi coding
agent to it. Run gmlx init with no flags for a wizard that scans the
folders where you already keep models.
To choose the optional features yourself, install with
uv tool install "gmlx[all]" and add brew install ffmpeg for voice.
Installation
covers both routes. Upgrade with brew upgrade gmlx, or
uv tool upgrade gmlx for a uv install. To remove gmlx, follow
Removing gmlx.
The Qwen3.8-27B UD-Q6_K file is 20.5 GB. A model needs memory for about its file size plus the conversation's KV cache, and Choosing a model in the Quickstart suggests models for each memory size.
Any GGUF file also runs, chats and serves by its path, with no configuration file:
gmlx run   Qwen3-4B-Q4_K_M.gguf --prompt "Explain entropy in one paragraph."
gmlx chat  Qwen3-4B-Q4_K_M.gguf
gmlx serve Qwen3-4B-Q4_K_M.gguf
A server started with one file names the model after the file without its
quant, here qwen3-4b, and uses it for a request that names no model.
run generates, benchmarks or prints the load plan of one file. chat is a
multi-turn terminal client with markdown rendering, sessions, live sampling
changes and image input. Both start from each model family's
recommended sampling,
and every flag is listed under its verb in the
CLI reference.
validate reads only a remote file's header to tell you whether it will load
and fit, and it can list the quants in a repo so you can pick one before
downloading anything. pull then fetches sharded files, resumes an
interrupted download and registers the result in your config.
One port serves OpenAI Chat Completions, OpenAI Responses and Anthropic
Messages, all streaming, with tool calling, structured output, logprobs and
vision messages. Concurrent requests decode together, a new prompt's prefill
is paced so that live replies keep streaming, and a prompt cache skips
repeated prefixes. The server binds loopback by default, requires a static
key or --no-auth for anything wider, and never downloads a chat model to
satisfy a request.
The endpoints are documented in the HTTP API, and
the file that configures them in
Configuration.
A served DiffusionGemma model also answers the Jev decision API at
/v1/systemone. A request asks a fixed set of yes or no, choice and score
questions about a state, and each answer comes back as a probability for
every option.
Structured decisions
shows how to write the questions and act on the answers.
gmlx launch pi --model qwen3.8-27b-ud-q6@coding writes the tool's
configuration so that it uses the server, starts the server first if it is
not running, and then runs the tool. gmlx launch works for the common
coding agents, two terminal chat clients and two browser apps, Open WebUI and
DeepSeek Harness, each listed with its quirks in Agents and chat apps.
A menu bar app shows what is resident, and gmlx service install keeps the
server running from login.
With gmlx talk a wake phrase opens the mic, Whisper transcribes, and the
reply is spoken as it streams, as
Voice chat
describes. The built-in assistant
adds MCP tools and long-term memory to a voice session, to
chat --assistant, and to assistant ids that the server exposes as models.
The server also exposes /v1/embeddings, /v1/rerank,
/v1/audio/transcriptions and /v1/audio/speech, which together give a
client like Open WebUI a local RAG and voice stack. The services are
described in
Speech, embeddings and rerank and
the RAG setup in RAG pipelines.
train fine-tunes through the quantized matmul, so a model too large for
memory in fp16 still trains, and it writes the adapter as a GGUF that
llama.cpp reads too. --adapter applies it at run, chat or serve, and one
base can serve several adapters at once, which
LoRA adapters walks through
end to end.
distill teaches a small GGUF what a larger one knows, a document or a
behavior. It trains an adapter on the larger model's outputs without
running the two at once, and
Distillation
gives the commands for each case.
Because gmlx and llama.cpp run the same file, the comparison is direct. On an
M5 Max, gmlx prefills faster on every benchmarked model at every depth, and
with speculative decoding on both engines it decodes faster at every depth as
well. Absolute numbers scale with the machine's memory bandwidth, so measure
your own with gmlx run model.gguf --bench 128,512,2048.
Performance tuning
covers the performance features. Speculative decoding uses a model's own
MTP head, or a companion drafter on models without one, and run and
chat turn it on by themselves. The prompt cache skips prefill for the
repeated prefixes of agent workloads, and KV-cache quantization shrinks long
contexts. Disk-streamed execution, described in
Models larger than memory,
runs MoE models larger than memory and makes a 200B-class model usable on a
64 GB machine.
The file you choose matters as well. A uniform K-quant decodes faster than a heavily mixed one at similar quality, and K-quants carry less error per byte than MLX's native quantization, as mlx-kquant explains.
A one-minute video shows the same server moving from one chat at full speculative speed to four concurrent streams and back, with no break in the live stream. Watch the concurrency video.
- Llama, Mistral, Phi-3, SmolLM3, Seed-OSS and ERNIE-4.5
- Qwen 2 through 3.8, dense and MoE, with the hybrid attention families
- Gemma 1 through 4, except the 3n variant, whose GGUFs are broken upstream
- DeepSeek V3, R1, V4-Flash and V4.1-Flash
- GLM 4 through 5.3, Kimi-K3, MiniMax M2 and M3, and gpt-oss
- Hunyuan, Hy3, HY4 and Muse Glimmer
- Granite, Nemotron-H and Falcon-H1
The generated coverage table lists each mapped architecture with its status and names the caveats where an architecture has any. A new family counts as done only after its output matches llama.cpp at 16k context, and Adding a GGUF architecture explains what adding a family involves.
All 19 K-quant, legacy and IQ codecs load, plus the MXFP4 and NVFP4 pair and the ternary STQ1_0, PTQ1_0 and PQ2_0 types. A vision model loads as a GGUF paired with its projector, as Vision and audio describes.
from gmlx import load_model, generate

model, config, tokenizer = load_model("model.gguf")
print(generate(model, tokenizer, "Explain entropy.", max_tokens=128))
load_model returns a ready-to-run mlx-lm model, the synthesized config and
the tokenizer. The full API, including preflight and the mlx-lm server bridge,
is in the Python API reference.
The documentation site publishes the pages listed here for the latest release, with navigation and search.
- Installation: Homebrew, uv and pip, the optional features, upgrading and removal.
- Quickstart: A first model, the server, a request and a connected client.
- Migrating from other tools: What carries over from llama.cpp, Ollama and LM Studio.
- Configuration:
gmlx.yaml, its models, its profiles and how a request gets its settings. - Agents and chat
apps: Claude Code,
other coding agents and Open WebUI, set up by
gmlx launch. - Menu bar app: Server status and controls in the macOS menu bar.
- Speech, embeddings and rerank: The services a server can host beside chat models.
- RAG pipelines: Retrieval with the embeddings and rerank services.
- Structured decisions: A probability for each answer to a fixed set of questions.
- Chat: The terminal chat client, its commands, sessions and themes.
- Voice chat: Talking
to a model with
gmlx talk. - Assistant: Tools and long-term memory for chat, voice and served models.
- Supported architectures: The GGUF architectures gmlx loads, with their caveats.
- Vision and audio:
Multimodal models and their
mmprojfiles. - Models larger than memory: Mixture-of-experts models that stream their experts from disk.
- LoRA adapters: Training an adapter and serving several on one base model.
- Distillation: Teaching a small model a document or a larger model's behavior.
- Performance tuning: What makes a model fast, measuring, and choosing a quant.
- Speculative decoding: Faster decoding with a drafter, with the same output.
- Prompt cache: Skipping prefill for prompts the server has seen.
- Concurrent requests: Batching, admission pacing and shared prompts.
- Memory and the KV cache: How much memory a model and its context take.
- KV cache quantization: Storing the context in fewer bits.
- Benchmarks: gmlx against llama.cpp on the same files, with the method.
- Troubleshooting:
gmlx doctor, common failures, and where gmlx keeps its files. - Glossary: The terms these pages use.
- CLI reference: Every command and flag.
- Configuration:
Every key of
gmlx.yaml. - Family defaults: The sampling defaults and intents of each model family.
- HTTP API: The endpoints and request features.
- Environment variables: The variables a user can set.
- Python API: Using gmlx from Python.
Pull requests are welcome. Dev setup and the rules are in the contributing guide, the test tiers in Testing, and the runtime's design in Internals.
gmlx builds on llama.cpp and ggml for the GGUF format and the K-quant reference implementations, MLX and mlx-lm for the runtime and model implementations, and mlx-vlm for the server app, generation step loop and vision towers. Speech uses mlx-whisper for speech-to-text and mlx-audio for text-to-speech.
gmlx is released under the Business Source License 1.1, which is source-available but not open source. You may use, modify and run gmlx for your own purposes, including commercial work, and you may redistribute unmodified copies free of charge. You may not sell gmlx or a derivative of it, incorporate either into a commercial product or service, or offer either to others as a hosted service. Each released version converts to the Apache License 2.0 four years after its release, and downloaded model weights have their own licenses.
The files listed in LICENSE-MIT are MIT licensed and have an SPDX header saying so. Vendored third-party code is documented in the third-party notices.